Your own endpoint
The phone gets one address on your network, locked with an API key. It handles chat, streamed replies and tool calls, just like any OpenAI-style API.
Early beta · 0.2.2Open sourceAndroid
Phonon runs an AI language model on an Android phone. Other programs on your home network can then use it, the same way they would use OpenAI's service — it offers an OpenAI-compatible API. There's no cloud and no subscription, and nothing leaves your house.
Needs: Android 10 or newer · 64-bit (arm64-v8a) · 8 GB of RAM for the small models
Obtainium installs the same APK and updates it when a new release comes out. That's the only reason it's here.
SHA-256 d59d829bcf77d15e65c91f0be25c62801330a2141bd22d4297047889e80e78ce
What you get
The phone gets one address on your network, locked with an API key. It handles chat, streamed replies and tool calls, just like any OpenAI-style API.
Pick from 5 model families (Qwen3.5, Gemma 4, MiniCPM5, Granite, Nemotron), 1.28 GB to 5.68 GB each. The app downloads the model and checks that the file is correct before using it.
Point any OpenAI-compatible tool at it — no code changes needed. Have two phones? They can work on two tasks at the same time.
Batches of agent work that run overnight. Private data that should stay in your house. Tinkering with a phone you already have.
Fast, back-and-forth chat, or models so big they need a graphics card (GPU). A phone answers one request at a time, and it is not fast.
Speed
An agent turn in 29 s on a Google Pixel 7.
One agent-shaped request — a system prompt and tool schemas of about 2,800 tokens, plus 128 generated tokens — through the app's own /v1.
Measured on Google Pixel 7 (measured with v0.1.14, not this build, 2026-10-19). docs/performance.md
Will my phone work?
Any phone with Android 10 or newer, a 64-bit ARM processor (arm64-v8a) and at least 8 GB of RAM for the small models should work. When the app starts, it checks the phone's processor and memory and tells you what it found. If the phone can't run a model, the app tells you why instead of just failing to start.
| Phone | RAM | Model | Speed | Status |
|---|---|---|---|---|
| Google Pixel 7Google Tensor G2 | 8 GB | Qwen3.5-2B-Q4_K_M | 14.01 tok/s | supported |
A phone is marked supported only after it has passed a fifteen-minute non-stop run. The rest are candidates, and they're labelled that way.
Google Pixel 7: measured with v0.1.14, 2026-10-19. devices/panther.yaml
What it serves
Each one is a different trade-off between speed, answer quality and memory. The note under each name says what it's best at.
| Model | Quant | Context | Download | Measured speed | Needs | Licence |
|---|---|---|---|---|---|---|
| Qwen3.5-2Bagent work: the fastest measured model, and the default | Q4_K_M | 32K | 1.28 GB | 9.20 / 8.84 tok/sPixel 7 | 8 GB RAM | Apache-2.0 |
| Qwen3.5-4Bbetter answers when speed matters less | Q4_K_M | 16K | 2.74 GB | 4.13 / 3.94 tok/sPixel 7 | 8 GB RAM | Apache-2.0 |
| Qwen3.5-9B12-16 GB phones only; unmeasured here | Q4_K_M | 48K | 5.68 GB | not measured | 16 GB RAM | Apache-2.0 |
| Gemma 4 E2Bvisionchat and images, at about two tok/s less than Qwen | Q4_0 | 16K | 2.84 GB | 7.05 / 6.74 tok/sPixel 7 | 8 GB RAM | Apache-2.0 |
| Gemma 4 E4Bvisionlarger Gemma; runs on 8 GB at 16K | Q4_0 | 16K | 4.59 GB | 4.12 / 3.85 tok/sPixel 7 | 8 GB RAM | Apache-2.0 |
| MiniCPM5-2Btool use per gigabyte, if its agent behaviour holds up | Q4_K_M | 32K | 1.56 GB | 6.82 / 6.57 tok/sPixel 7 | 8 GB RAM | Apache-2.0 |
| Granite 4.2 3Btool calling on IBM's line; about half Qwen's speed | Q4_K_M | 32K | 2.24 GB | 4.41 / 4.39 tok/sPixel 7 | 8 GB RAM | Apache-2.0 |
| Nemotron 3 Nano 4Bslowest measured; offered for completeness | Q4_K_M | 32K | 2.84 GB | 3.57 / 3.46 tok/sPixel 7 | 8 GB RAM | NVIDIA Open Model Licensenot OSI-approved |
Sizes, contexts, licences and speeds come from catalog.json at the tag. The measured speeds are Pixel 7 runs; see docs/models.md.
Set up
http://<phone>:8080/v1 with your key. Running more than one phone? Add LiteLLM in front.Your API key is sent unencrypted.
Phonon uses plain HTTP, not HTTPS. That means your key and everything you send cross your network without encryption. Keep the phone on a network you trust, and never open it up to the internet with port forwarding.
These come straight from the app repository at v0.2.2.
{
  "$schema": "https://opencode.ai/config.json",
  "model": "phone/gemma-4-e2b",
  "small_model": "phone/gemma-4-e2b",
  "default_agent": "phone-coder",
  "autoupdate": false,
  "share": "disabled",
  "provider": {
    "litellm": {
      "npm": "@ai-sdk/openai-compatible",
      "name": "Phone pool (LiteLLM)",
      "options": {
        "baseURL": "http://litellm.lan:4000/v1",
        "apiKey": "{env:LITELLM_KEY}",
        "timeout": 1800000,
        "headerTimeout": 900000,
        "chunkTimeout": 600000
      },
      "models": {
        "phone-a": {
          "name": "Pixel 7 #1 (pinned)",
          "tool_call": true,
          "reasoning": false,
          "limit": {
            "context": 32768,
            "output": 2048
          }
        },
        "phone-b": {
          "name": "Pixel 7 #2 (pinned)",
          "tool_call": true,
          "reasoning": false,
          "limit": {
            "context": 32768,
            "output": 2048
          }
        },
        "gemma-4-e2b": {
          "name": "Phone pool (any)",
          "tool_call": true,
          "reasoning": false,
          "limit": {
            "context": 32768,
            "output": 2048
          }
        }
      }
    },
    "phone": {
      "npm": "@ai-sdk/openai-compatible",
      "name": "Phone (LAN llama.cpp)",
      "options": {
        "baseURL": "http://phone.lan:8080/v1",
        "apiKey": "{env:PHONE_KEY}",
        "timeout": 1800000,
        "headerTimeout": 900000,
        "chunkTimeout": 600000
      },
      "models": {
        "gemma-4-e2b": {
          "name": "Gemma 4 E2B (phone)",
          "tool_call": true,
          "reasoning": false,
          "limit": {
            "context": 32768,
            "output": 2048
          }
        }
      }
    }
  },
  "permission": {
    "*": "allow",
    "external_directory": "deny",
    "webfetch": "deny"
  },
  "tools": {
    "webfetch": false,
    "task": false,
    "skill": false,
    "todowrite": false,
    "glob": false,
    "grep": false
  },
  "agent": {
    "phone-coder": {
      "description": "Small mechanical coding tasks on a slow local model",
      "model": "phone/gemma-4-e2b",
      "prompt": "You are a careful, slow coding worker. You receive one small task. Do exactly that task and nothing else.\n\nRules:\n- Read only the files you need. Do not explore the repository.\n- Change as few files as possible; one file is the normal case.\n- Do not refactor, rename broadly, reformat, or 'improve' unrelated code.\n- To search, use bash: `grep -rn \"pattern\" .` or `find . -name \"*.py\"`.\n- Do not run git. The runner handles branches and commits.\n- Run the check command the task gives you.\n- If the check fails, fix your change if the cause is obvious; otherwise stop and say what failed.\n- When the task is complete, reply with one short paragraph: what you changed, and the check result.",
      "tools": {
        "webfetch": false,
        "task": false,
        "skill": false,
        "todowrite": false,
        "glob": false,
        "grep": false
      }
    }
  }
}# LiteLLM gateway for the phone lane.
#
# Template: YAML-valid and used for the two-phone bring-up. Re-check the
# `router_settings` keys against the installed LiteLLM on upgrade — some have
# moved between releases.
#
# Two naming layers, deliberately:
# phone-a / phone-b : pinned, one deployment each. Use these for agent tasks
# so every turn hits the same llama-server KV cache.
# qwen3.5-2b : pooled, both deployments. Use for one-shot calls that
# have no prefix worth preserving.
#
# The same endpoint appears twice (pinned and pooled). That is intentional:
# model_name is the routing group, litellm_params is the deployment.
model_list:
# ---- Pixel 7 #1 -------------------------------------------------------
- model_name: phone-a
litellm_params:
model: openai/qwen3.5-2b
api_base: http://phone-a.lan:8080/v1
api_key: os.environ/PHONE_A_KEY
timeout: 1800
stream_timeout: 1800
max_retries: 0
- model_name: gemma-4-e2b
litellm_params:
model: openai/qwen3.5-2b
api_base: http://phone-a.lan:8080/v1
api_key: os.environ/PHONE_A_KEY
timeout: 1800
stream_timeout: 1800
max_retries: 0
# ---- Pixel 7 #2 -------------------------------------------------------
- model_name: phone-b
litellm_params:
model: openai/qwen3.5-2b
api_base: http://phone-b.lan:8080/v1
api_key: os.environ/PHONE_B_KEY
timeout: 1800
stream_timeout: 1800
max_retries: 0
- model_name: gemma-4-e2b
litellm_params:
model: openai/qwen3.5-2b
api_base: http://phone-b.lan:8080/v1
api_key: os.environ/PHONE_B_KEY
timeout: 1800
stream_timeout: 1800
max_retries: 0
router_settings:
routing_strategy: least-busy
# A phone takes minutes to first token and can spend half an hour on a task.
# Cloud-shaped defaults would abort healthy requests and cool the phone down.
timeout: 1800
num_retries: 0
allowed_fails: 5
cooldown_time: 60
# Sticky routing, if the client ever sends a session id
# (x-litellm-session-id, or metadata.session_id in the body).
# opencode does not send one by default, which is why the runner pins.
optional_pre_call_checks: ["session_affinity"]
deployment_affinity_ttl_seconds: 3600
litellm_settings:
# This template deliberately configures no background health checks. A phone
# busy generating has no spare slot to answer a probe, so a completions-based
# check reports a healthy node as dead and takes it out of rotation. Leave the
# proxy's checks off until there is a cheap, non-completion probe wired to
# llama-server's /health.
request_timeout: 1800
drop_params: true
See it
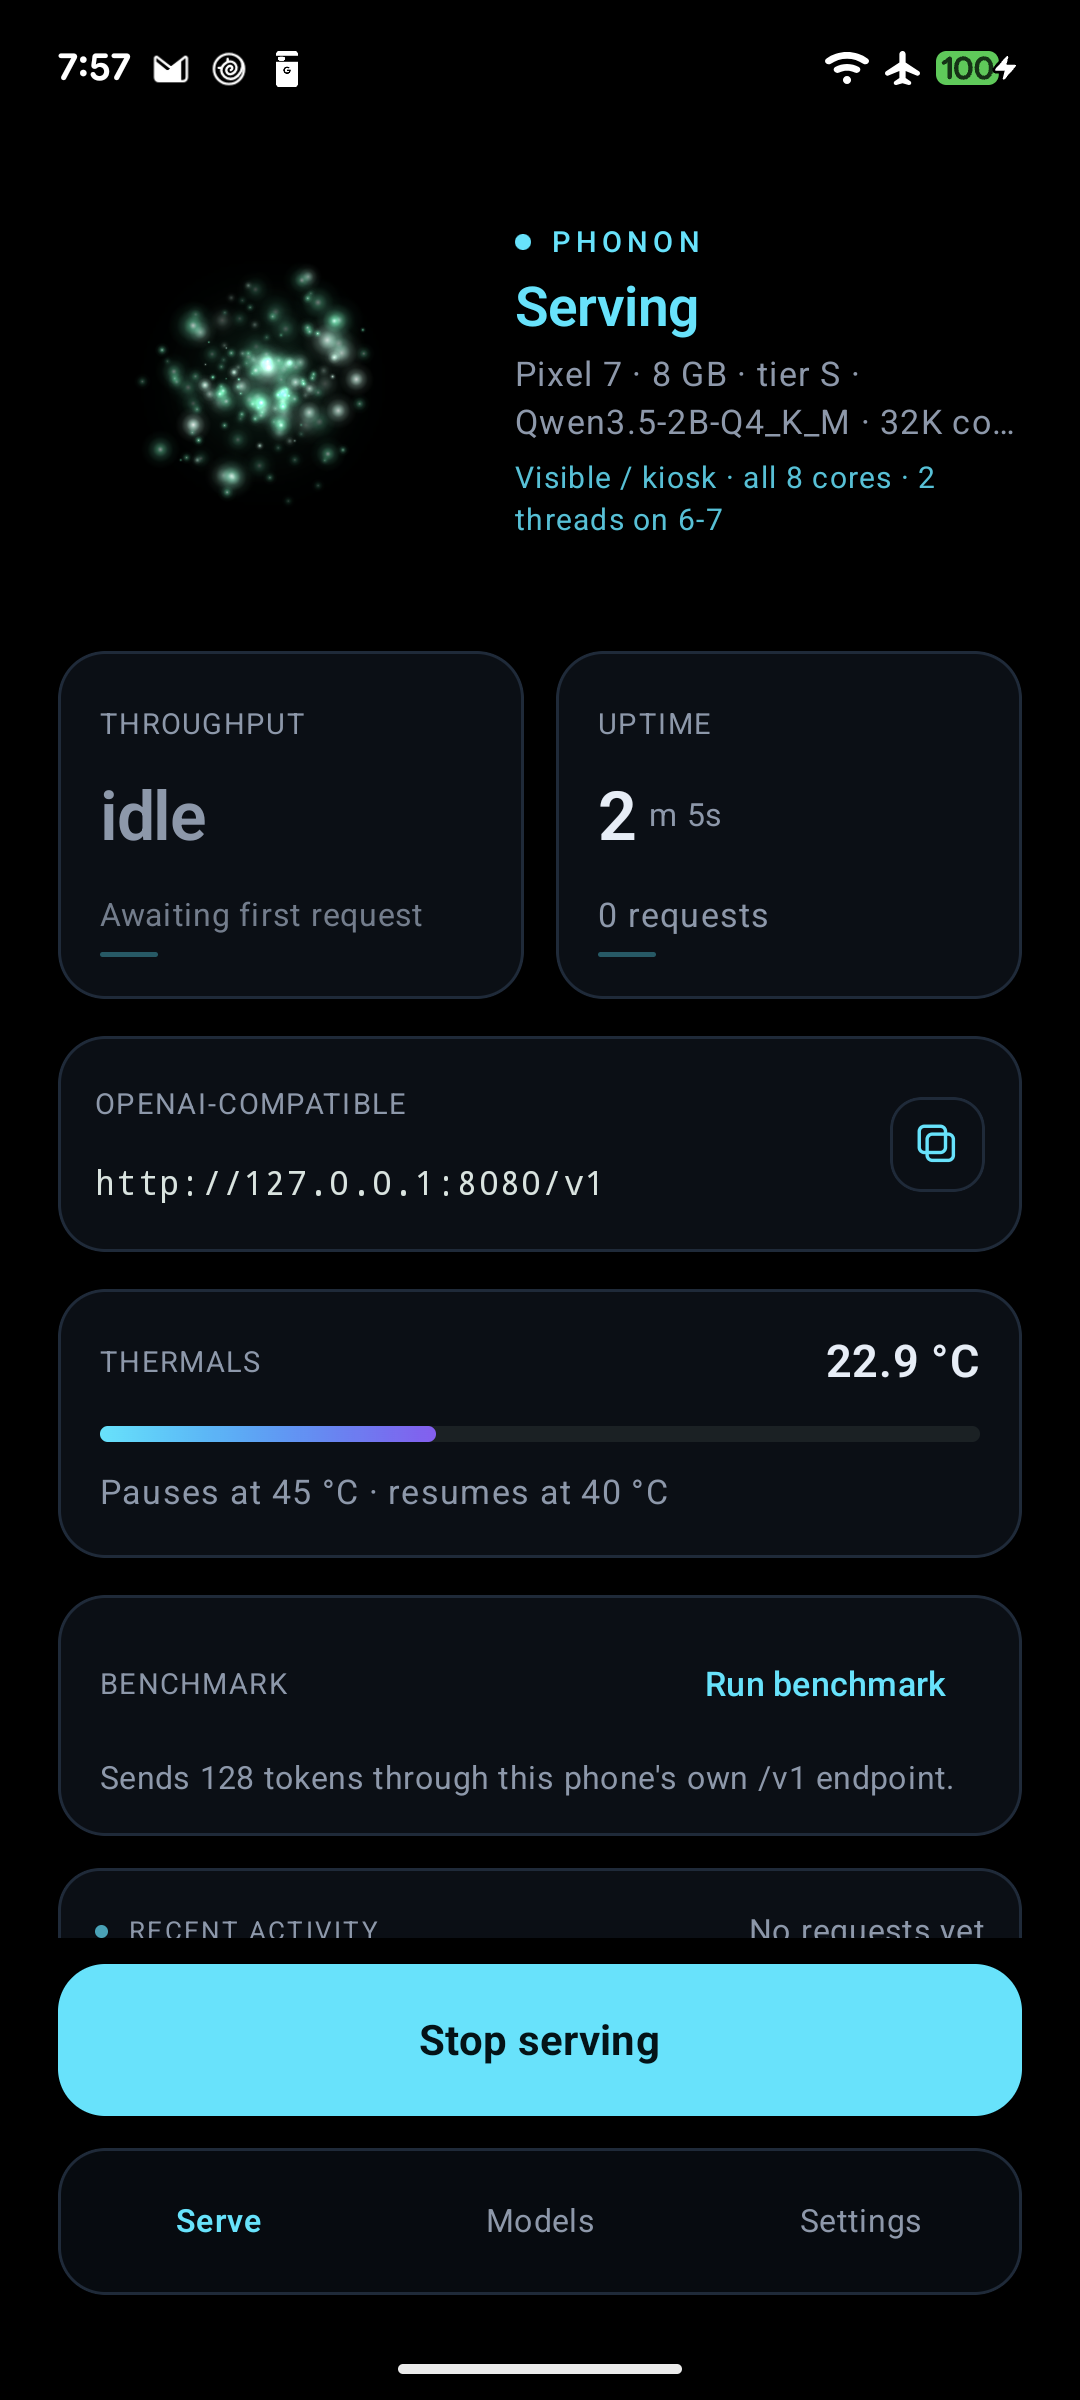
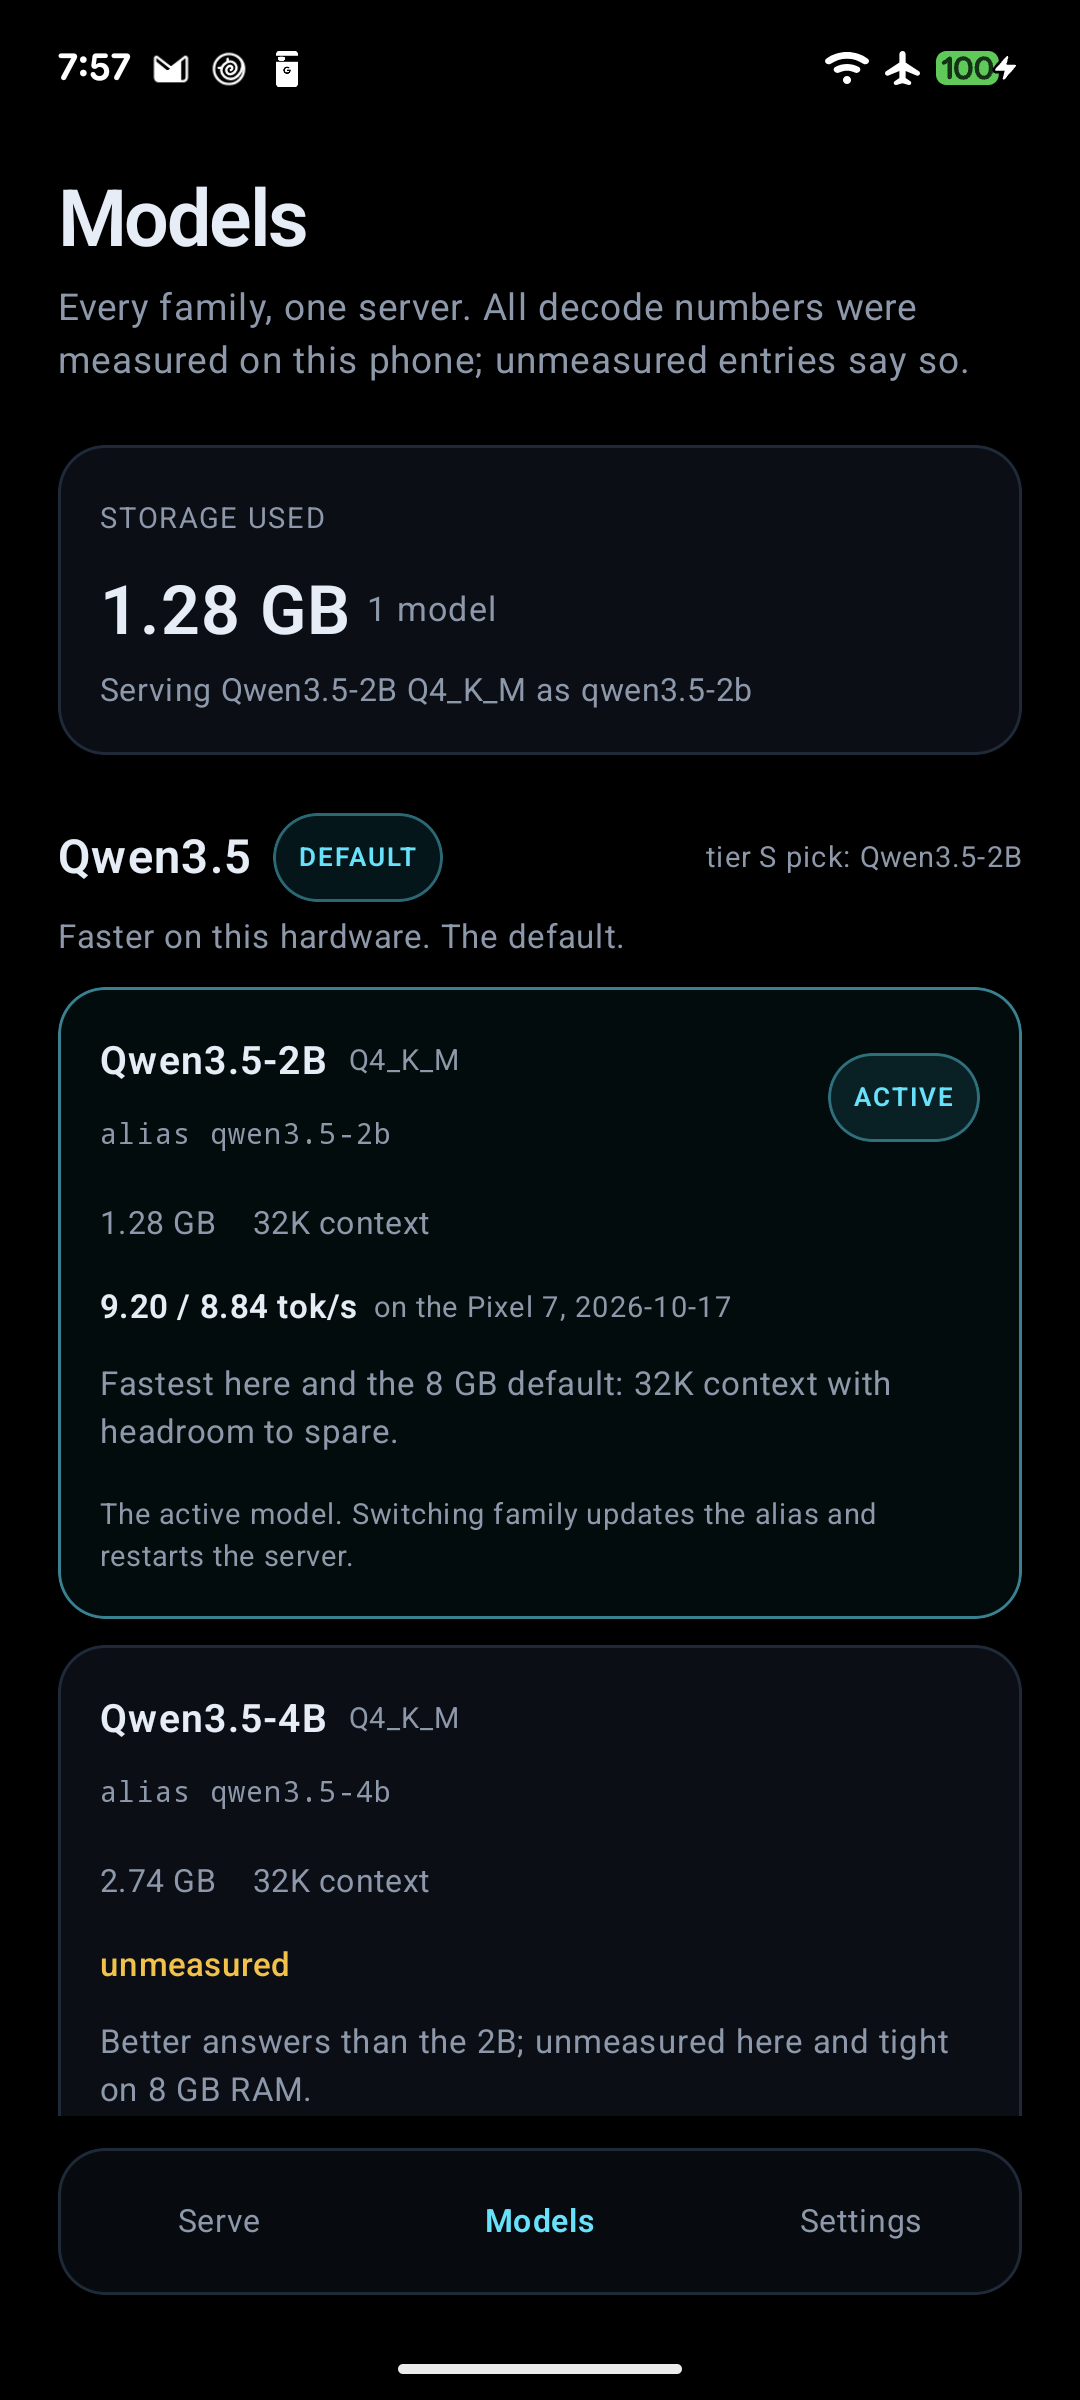
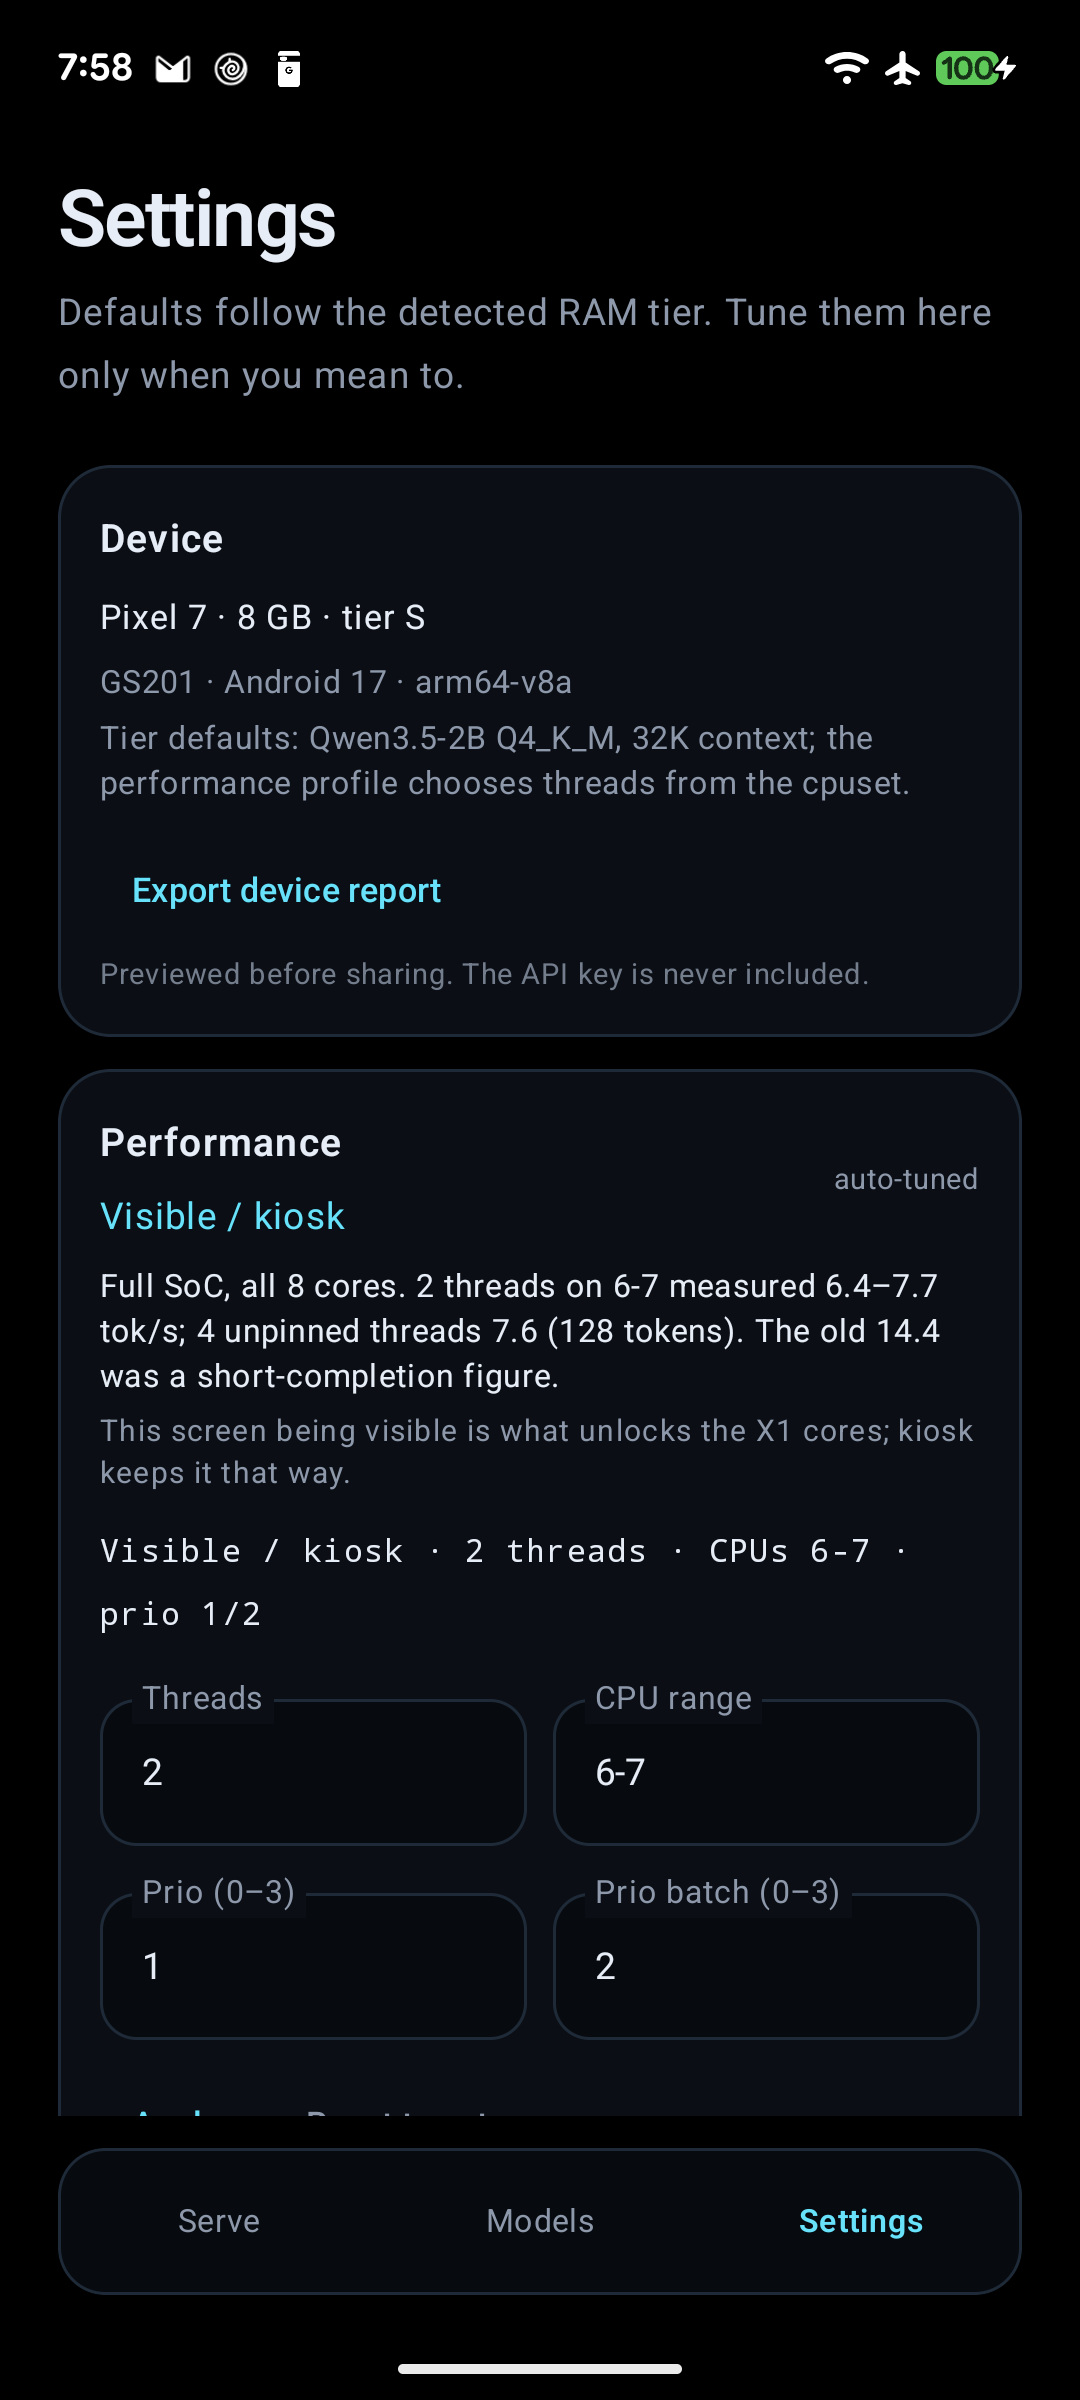
These are the app's own fastlane screenshots at v0.2.2, copied into this build — not a saved copy that could go stale.
Release notes
Fixes the launcher icon. 0.2.1 shipped a different mark — three squares in the wrong arrangement with a square node — while the app itself drew the BENCH mark. The icon is now generated from the same coordinates as the logo: open square, round lamp, on the CORE ground.
Fixes an update-path hang. A server started by the previous build survives the update, keeps the backend port, and the new process could not start its own — the screen sat on STARTING indefinitely. The supervisor now reaps a server it did not start before launching.
A new identity, and three things that make the node easier to live with.
- CORE: a thermal-readout look — hard edges, condensed display type, light and dark following the system, the BENCH mark as the logo and the launcher icon. - The mark is alive: it draws the bus, runs a packet along the traces and turns its corners; green means serving, amber means paused on heat, red means a fault. - Home Assistant: the built-in Ollama integration now finds this node — a conversation agent and Assist, with no extra software to install. - Battery: a charging-limit card that opens the system screen, confirms the state, and reports hours spent above 80% this week. - Gateway: optional one-switch LiteLLM registration with the key encrypted on the device. - Model downloads: memory pressure now warns with the numbers and lets you continue, instead of refusing the download outright.
Taken from the release notes at the tag, not written for this page.
Where the numbers come from
Every figure on this page is read from a file in the app's repository at v0.2.2 when the page is built. If a value is missing there, the page says so instead of making one up.
Status
Early beta · 0.2.2
Phonon is new software. The measurements on this page are real, but the app will have rough edges. Expect things to break, and please report it when they do.